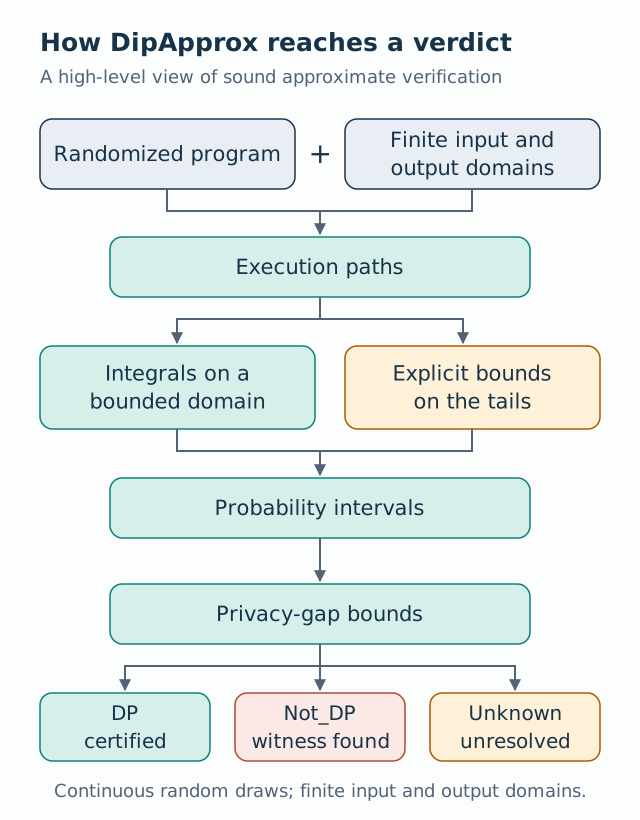
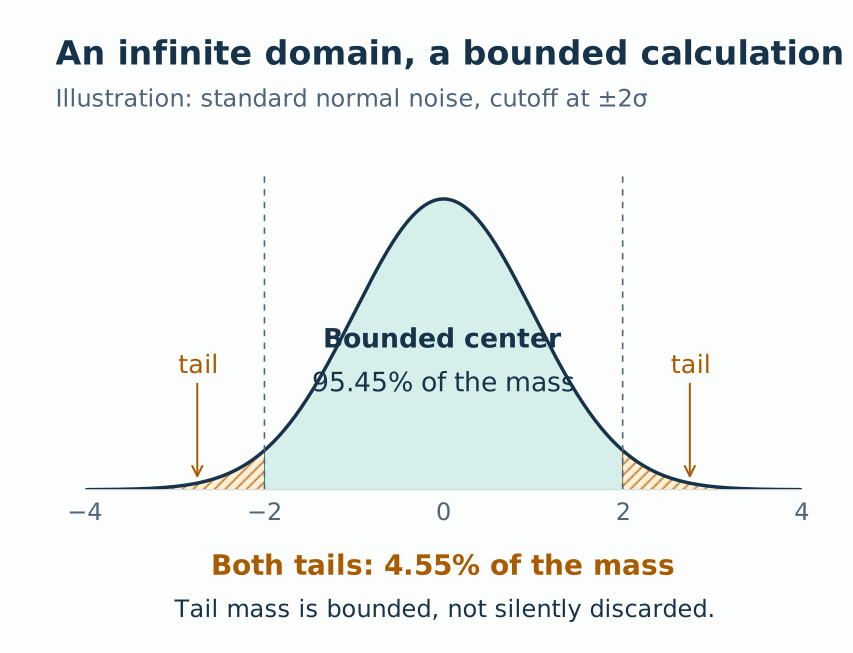
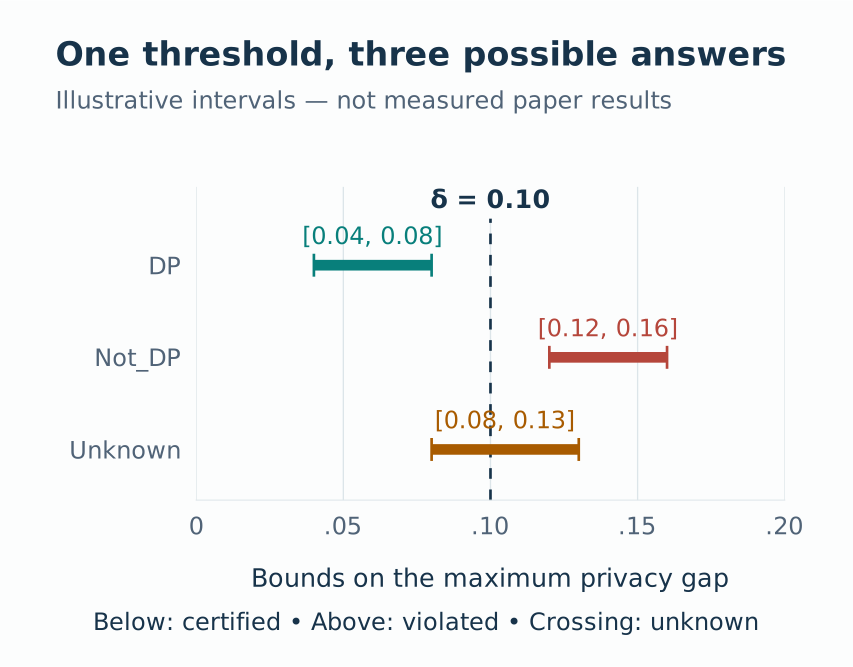
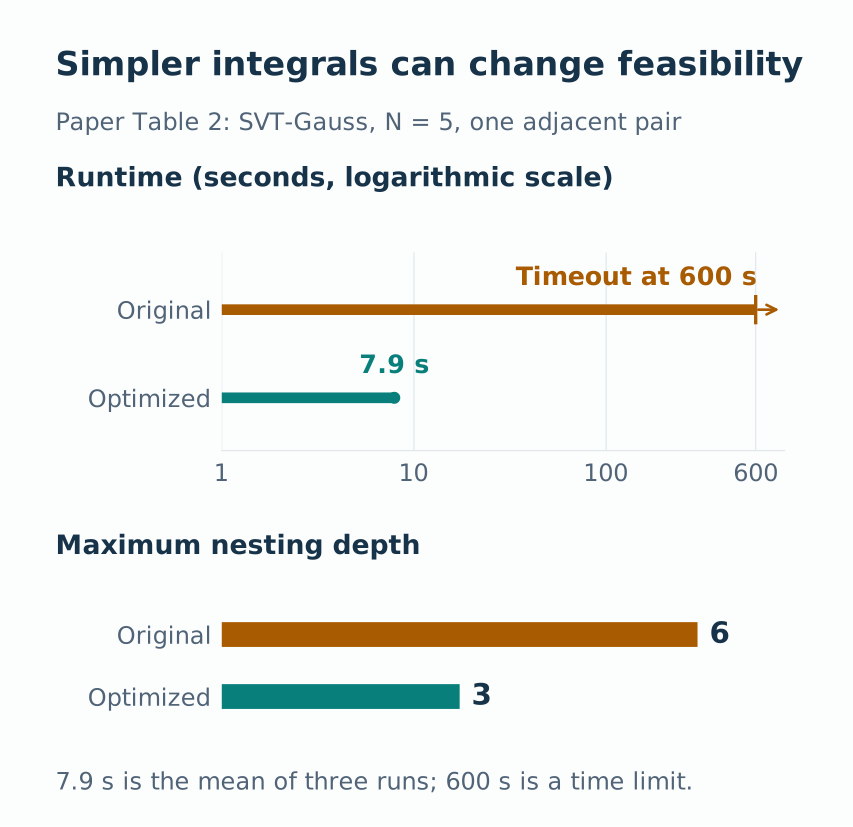
<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en"><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://bishnubhusal.com.np/feed.xml" rel="self" type="application/atom+xml"/><link href="https://bishnubhusal.com.np/" rel="alternate" type="text/html" hreflang="en"/><updated>2026-10-22T16:58:00-06:00</updated><id>https://bishnubhusal.com.np/feed.xml</id><title type="html">Bishnu Bhusal</title><subtitle>Bishnu Bhusal is a computer science researcher working on differential privacy, formal verification, and privacy-preserving machine learning and LLMs. Publications at ACM CCS, AAAI, and OOPSLA.</subtitle><entry><title type="html">Why gradient clipping changes Muon’s geometry: a two-dimensional example</title><link href="https://bishnubhusal.com.np/blog/2026/clipping-geometry-private-muon/" rel="alternate" type="text/html" title="Why gradient clipping changes Muon’s geometry: a two-dimensional example"/><published>2026-10-17T09:00:00-06:00</published><updated>2026-10-17T09:00:00-06:00</updated><id>https://bishnubhusal.com.np/blog/2026/clipping-geometry-private-muon</id><content type="html" xml:base="https://bishnubhusal.com.np/blog/2026/clipping-geometry-private-muon/"><![CDATA[<p>Per-example gradient clipping changes more than an update’s size. Although clipping multiplies each example’s gradient by a nonnegative scalar, different examples generally receive different scalars. Their average can therefore point in a different direction or, for matrix-valued gradients, have different singular-vector geometry.</p> <p>Our preprint <a href="/publications/bhusal2026dpmuon/"><em>Inner Momentum for Differentially Private Muon</em></a> investigates why this matters for Muon and proposes a history-based correction before clipping. This tutorial uses the preprint’s abstract to describe its motivation and reported scope. The calculation below is an independent illustration, not a reproduction of its algorithm, theoretical bounds, or experiments. The source is available on <a href="https://arxiv.org/abs/2610.02738">arXiv</a>.</p> <h2 id="why-a-matrix-optimizer-notices-clipping">Why a matrix optimizer notices clipping</h2> <p>A matrix A can be written using a singular value decomposition as U Sigma V-transpose. For a nonsingular square matrix, its orthogonal polar factor is Q = U V-transpose. This retains singular-vector information while replacing singular values by one. Muon’s orthogonalization is motivated by an approximation to this polar factor.</p> <p>Multiplying A by the same positive scalar changes its singular values but preserves Q. That invariance can make clipping seem harmless at first: if clipping just scales the update, why would the orthogonalized update change?</p> <p>The missing distinction is the order of operations. Private training clips individual examples before averaging them. If their clipping multipliers differ, the clipped mean need not be a scalar multiple of the original mean. Orthogonalization can therefore see a different input geometry even before privacy noise is added.</p> <h2 id="two-matrices-are-enough">Two matrices are enough</h2> <p>Consider two illustrative per-example matrix gradients:</p> \[G_1 = \begin{pmatrix} 4 &amp; 0 \\ 0 &amp; 0 \end{pmatrix}, \qquad G_2 = \begin{pmatrix} 0 &amp; 1 \\ 0 &amp; 1 \end{pmatrix}.\] <p>Their arithmetic mean is</p> \[A = \frac{G_1 + G_2}{2} = \begin{pmatrix} 2 &amp; 0.5 \\ 0 &amp; 0.5 \end{pmatrix}.\] <p>Clip each matrix to Frobenius norm at most 1. The Frobenius norm is the square root of the sum of squared entries. The clipping operation multiplies G by min(1, 1 / norm(G)), leaving a zero matrix unchanged.</p> <p>The two norms are 4 and square-root-of-2, so the clipping multipliers are 0.25 and approximately 0.707107. After clipping each example and then averaging, the result is</p> \[B = \begin{pmatrix} 0.5 &amp; 0.353553\ldots \\ 0 &amp; 0.353553\ldots \end{pmatrix}.\] <p>B is not a common rescaling of A. Its first column shrank more than its second because the examples contributing to those columns had different norms. This reweighting occurs before we add any noise or run any approximate orthogonalization routine.</p> <figure> <img src="/assets/img/research/muon-clipping-matrices.svg" width="640" height="650" class="img-fluid" loading="lazy" data-zoomable="" alt="Two example gradients receive different clipping multipliers: 0.25 and about 0.7071. Their original mean is [[2, 0.5], [0, 0.5]], while the mean after clipping is about [[0.5, 0.3536], [0, 0.3536]]."/> <figcaption><strong>Figure 1.</strong> Clipping each example changes its contribution to the mean. The first example is reduced more strongly, so the two columns do not shrink by a common factor. Values come from the illustrative matrices above.</figcaption> </figure> <h2 id="compute-the-polar-factor-rotation">Compute the polar-factor rotation</h2> <p>For a real 2-by-2 matrix with entries a, b, c, d and positive determinant, its polar factor has a convenient closed form:</p> \[Q = \frac{1}{\sqrt{(a + d)^2 + (c - b)^2}} \begin{pmatrix} a + d &amp; b - c \\ c - b &amp; a + d \end{pmatrix}.\] <p>Its rotation angle is atan2(c − b, a + d). Both means in this example have positive determinants, so the formula applies even though the individual example matrices are rank deficient.</p> <table> <thead> <tr> <th style="text-align: left">Matrix sent to orthogonalization</th> <th style="text-align: right">Polar-factor rotation</th> </tr> </thead> <tbody> <tr> <td style="text-align: left">Original mean A</td> <td style="text-align: right">−11.309932 degrees</td> </tr> <tr> <td style="text-align: left">Mean of clipped examples B</td> <td style="text-align: right">−22.500000 degrees</td> </tr> <tr> <td style="text-align: left">Common rescaling 0.25A</td> <td style="text-align: right">−11.309932 degrees</td> </tr> </tbody> </table> <p>The unequal clipping changes the polar rotation by about 11.19 degrees. Common positive rescaling leaves it unchanged. The Frobenius distance between the two polar factors is approximately 0.275762. These are deterministic properties of the chosen matrices, not measured training improvements.</p> <figure> <img src="/assets/img/research/muon-polar-rotation.svg" width="640" height="500" class="img-fluid" loading="lazy" data-zoomable="" alt="The original polar factor rotates the first unit vector by minus 11.31 degrees; after per-example clipping, the rotation is minus 22.50 degrees, a difference of 11.19 degrees. Common positive rescaling preserves the original rotation."/> <figcaption><strong>Figure 2.</strong> Each arrow shows where a polar factor sends the first unit vector. These are unit directions after orthogonalization; their lengths do not represent gradient magnitudes.</figcaption> </figure> <p>Download <a href="/assets/code/clipping_polar_geometry.py">clipping_polar_geometry.py</a> and run it with Python’s standard library:</p> <div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>python3 clipping_polar_geometry.py
</code></pre></div></div> <p>The script prints the clipping multipliers, both means, their rotations, and the common-rescaling control. It intentionally handles only the positive-determinant 2-by-2 case needed here. It is not a general SVD implementation or a private optimizer.</p> <h2 id="explore-the-clipping-threshold">Explore the clipping threshold</h2> <p>Let \(C&gt;0\) be the clipping threshold. For these two matrices, thresholds at or below \(\sqrt{2}\) give both clipped examples norm \(C\) and produce the same polar rotation of −22.5°. Between \(\sqrt{2}\) and 4, only the first example is clipped, so the angle moves toward the original −11.31°. At \(C\geq4\), neither example is changed.</p> <figure> <img src="/assets/img/research/muon-clipping-sweep.svg" width="640" height="550" class="img-fluid" loading="lazy" data-zoomable="" alt="Polar rotation versus clipping threshold C: minus 22.5 degrees up to square root of two, then approaching the original minus 11.31 degrees at C equal to four, where clipping stops. The worked example uses C equal to one."/> <figcaption><strong>Figure 3.</strong> Changing the threshold changes the geometry of the same two example matrices. The curve is calculated directly from their polar factors.</figcaption> </figure> <div class="muon-explorer" data-muon-explorer="" hidden=""> <h3>Try a clipping threshold</h3> <label for="muon-clipping-threshold">Threshold C: <output data-muon-threshold="" aria-live="off">1.00</output></label> <input id="muon-clipping-threshold" type="range" min="0.25" max="4.5" step="0.05" value="1" aria-describedby="muon-threshold-help"/> <p id="muon-threshold-help">Move the slider to change how strongly each example is clipped.</p> <div class="muon-explorer-presets"> <button type="button" data-muon-preset="1">Example: C = 1</button> <button type="button" data-muon-preset="4">No clipping: C = 4</button> </div> <div class="muon-explorer-values"> <div> <p>Mean after clipping</p> <table class="muon-explorer-matrix" aria-label="Mean matrix after clipping"> <tbody> <tr> <td data-muon-a="">0.5000</td> <td data-muon-b="">0.3536</td> </tr> <tr> <td>0.0000</td> <td data-muon-d="">0.3536</td> </tr> </tbody> </table> </div> <div> <p>Polar rotation</p> <output data-muon-angle="" aria-live="off">−22.50°</output> </div> <div> <p>Change from original</p> <output data-muon-change="" aria-live="off">11.19°</output> </div> </div> <p class="muon-explorer-note">Rounded values for the same two example matrices. No privacy noise is added.</p> <span class="sr-only" data-muon-status="" role="status"></span> </div> <script defer="" src="/assets/js/muon_clipping_explorer.js?abcc187f9005bee7d7df7d1f1e6193a4"></script> <h2 id="the-connection-to-inner-momentum">The connection to inner momentum</h2> <p>The preprint proposes averaging each sampled example’s Muon gradient over the current model and a short history of recent models before clipping. This places the temporal averaging inside the per-example computation. It differs from simply smoothing a batch update after clipping has already reweighted its contributors.</p> <p>A useful algebraic view separates common scaling from the part that changes geometry. Write a clipped mean as the average of alpha-i times G-i, where alpha-i is an example’s clipping multiplier. If alpha-bar and G-bar are their respective averages, then</p> \[\frac1n \sum_i \alpha_i G_i = \bar\alpha \bar G + \frac1n \sum_i (\alpha_i - \bar\alpha)(G_i - \bar G).\] <p>The first term is a common rescaling. The second is a covariance-like residual that captures the association between gradient structure and clipping multipliers. The abstract describes a distortion bound using such a residual. The identity alone does not prove that any particular temporal averaging scheme reduces it.</p> <p>The abstract also states that a finite Newton–Schulz iteration preserves the input polar factor under specified spectral conditions. That statement needs those conditions; this example’s exact closed form does not test a finite-iteration implementation.</p> <h2 id="what-the-preprint-reports">What the preprint reports</h2> <p>The abstract reports GPT-2 fine-tuning on E2E and DART at epsilon values 1, 2, 4, and 8. It states that DP-Muon-IM improves BLEU and ROUGE-L over DP-Muon in every seed-matched comparison in those experiments, and reports 2–4% lower pre-noise polar error in non-private diagnostics. These are the authors’ reported results for the preprint’s evaluation, not a guarantee for other models or datasets.</p> <p>This illustrative calculation adds no privacy noise and performs no training. Clipping alone is insufficient to establish differential privacy. A private implementation must analyze the full mechanism, including its noise, sampling, history dependence, and privacy accounting.</p> <h2 id="when-to-cite-this-work">When to cite this work</h2> <p>Cite <a href="/publications/bhusal2026dpmuon/"><em>Inner Momentum for Differentially Private Muon</em></a> when discussing its proposed per-example history averaging, its analysis of clipping-induced polar distortion, or comparisons to DP-Muon-IM. Identify it as an arXiv preprint and consult the current version for the exact assumptions and implementation. The elementary matrix example here explains the motivation; it does not establish the proposed method’s effectiveness.</p>]]></content><author><name>Bishnu Bhusal</name></author><category term="research"/><category term="differential-privacy"/><category term="optimization"/><category term="language-models"/><category term="python"/><summary type="html"><![CDATA[A runnable Python example shows how unequal per-example clipping rotates a matrix's polar factor, motivating the DP-Muon-IM preprint.]]></summary></entry><entry><title type="html">Privacy-preserving in-context learning: synthetic demonstrations and privacy budgets</title><link href="https://bishnubhusal.com.np/blog/2026/privacy-preserving-in-context-learning/" rel="alternate" type="text/html" title="Privacy-preserving in-context learning: synthetic demonstrations and privacy budgets"/><published>2026-09-08T09:00:00-06:00</published><updated>2026-09-08T09:00:00-06:00</updated><id>https://bishnubhusal.com.np/blog/2026/privacy-preserving-in-context-learning</id><content type="html" xml:base="https://bishnubhusal.com.np/blog/2026/privacy-preserving-in-context-learning/"><![CDATA[<p>In-context learning gives a language model examples inside a prompt, allowing it to perform a task without updating its weights. When those examples contain private records, the prompt becomes part of the privacy problem. A model can repeat sensitive phrases, and simply asking it to paraphrase does not provide a mathematical privacy guarantee.</p> <p>Our AAAI 2026 paper, <a href="/publications/bhusal2026aaai/"><em>Privacy Preserving In-Context-Learning Framework for Large Language Models</em></a>, studies a different workflow: generate synthetic demonstrations through a differentially private mechanism, then reuse those demonstrations for downstream inference. This tutorial explains the mechanism and the boundary of its guarantee. The <a href="/assets/pdf/aaai26.pdf">paper PDF</a> and <a href="https://github.com/bhusalb/privacy-preserving-icl">research code</a> provide the full method.</p> <h2 id="what-is-being-protected">What is being protected?</h2> <p>Differential privacy bounds how much an output distribution can change when one protected record changes. The paper uses add/remove adjacency: two datasets are neighbors when one contains one additional prompt record. A mechanism A is (epsilon, delta)-differentially private if, for every neighboring pair and every output event S,</p> \[\Pr[A(D)\in S]\leq e^{\varepsilon}\Pr[A(D')\in S]+\delta.\] <p>The guarantee concerns distributions, including unlikely outputs. It does not promise that sensitive-looking words can never appear. Delta is an additive allowance in this inequality; it should not be interpreted as the probability that a particular person’s record will be exposed. For the formal definition and post-processing property, see Chapter 2 of Dwork and Roth’s <a href="https://www.cis.upenn.edu/~aaroth/Papers/privacybook.pdf"><em>The Algorithmic Foundations of Differential Privacy</em></a>.</p> <p>The protected unit matters. If one person contributes many prompt records, a record-level guarantee is not automatically the same as a user-level guarantee. Deployment requires choosing the unit of protection before calibrating the mechanism.</p> <h2 id="how-private-demonstrations-are-generated">How private demonstrations are generated</h2> <p>The paper’s generator consults several private prompts separately. At each decoding step, the language model produces a vector of logits for each prompt, conditioned on the synthetic prefix generated so far. A logit is a score for a possible next token, before conversion into probabilities.</p> <p>The algorithm recenters and clips each logit vector, then averages the clipped private vectors. Bounding each vector’s coordinates controls the influence of one private prompt. Recentering and clipping have different effects: a uniform shift leaves softmax probabilities unchanged, while clipping can change them.</p> <p>A second branch computes clipped logits using a public prompt and the same synthetic prefix. The algorithm averages the public vector with the private aggregate, then samples a token using temperature-scaled softmax. The paper analyzes this sampling through the exponential mechanism. It does not implement this step by adding Gaussian noise to logits.</p> <p>The sampled token extends the prefix, and generation continues until an end-of-sequence token or a specified maximum length. The resulting synthetic examples become demonstrations for downstream ICL. No fine-tuning of the underlying language model is required by this workflow.</p> <p>Public blending is useful because a language model’s public context can support task-relevant tokens without another direct consultation of private records. However, blending an unprotected private vector with a public vector does not, by itself, establish privacy. The guarantee depends on the sensitivity bound and randomized sampling together.</p> <h2 id="where-composition-enters">Where composition enters</h2> <p>Every new token can depend on the private prompts. Privacy accounting must therefore cover the whole sequence, including its adaptive dependence on earlier tokens.</p> <p>A conservative calculation uses basic composition, developed alongside stronger composition results in Chapter 3 of <a href="https://www.cis.upenn.edu/~aaroth/Papers/privacybook.pdf">Dwork and Roth</a>. If each of T token mechanisms is epsilon-zero DP, with that guarantee holding conditional on every prior transcript, releasing the sequence is at most T times epsilon-zero DP. For example, 40 steps with a per-step budget of 0.02 give an overall bound of 0.8. These numbers illustrate composition; they are not settings or results from the paper.</p> <p>More refined composition can improve the bound by allowing a nonzero delta. Any implementation must retain the terms and assumptions of the chosen accounting theorem. A useful operating rule is to set a maximum number of private token-generation steps before generation begins. Generating several synthetic examples from the same records also requires accounting across those examples, not just within each one.</p> <p>Reusing a fixed, privately generated demonstration set is different. If subsequent inference uses only that release and information independent of the protected records, differential privacy’s post-processing property adds no privacy cost for those records. Creating a fresh demonstration set by consulting the records again is a new private computation.</p> <h2 id="the-public-branch-and-the-trust-boundary">The public branch and the trust boundary</h2> <p>The public branch can depend on the already generated private transcript. For analysis, one fixes that transcript and asks whether the branch makes any additional access to the protected dataset. A public prompt chosen from raw private records, or a model separately fine-tuned on those records without accounting, requires additional analysis.</p> <p>The mechanism protects what is released through its analyzed output interface. The machine computing raw private logits still sees private prompts. Sending those prompts to a remote inference provider exposes them to that provider unless the deployment establishes a separate protection. Output DP does not make the raw prompts invisible to the service running inference.</p> <p>Similarly, downstream queries may themselves contain sensitive information. The guarantee for the demonstration records does not automatically cover those queries. Logging raw prompts or intermediate unprotected logits also creates an output channel outside the intended release.</p> <h2 id="what-the-experiments-establish">What the experiments establish</h2> <p>The paper evaluates synthetic demonstrations on AGNews, DBPedia, and TREC classification, plus MIT-G and MIT-D extraction tasks. Its main experiments use Gemma 1.1 2B IT and access to full token logits. At epsilon equal to 1, Table 1 reports better accuracy than the two Gemma-based baselines on three of the five tasks; performance is not uniformly best across all tasks.</p> <p>These results support studying private prediction as a way to obtain useful demonstrations. They do not establish that arbitrary models, prompts, or application domains will have the same utility. An API exposing only generated text or a few token probabilities may also lack the interface required by the described method.</p> <h2 id="when-to-cite-this-work">When to cite this work</h2> <p>Cite the <a href="/publications/bhusal2026aaai/">AAAI paper</a> when discussing private synthetic demonstrations for ICL, clipped logit aggregation with public-context blending, or reproducing and comparing this framework. Use the <a href="https://doi.org/10.1609/aaai.v40i42.40838">published DOI</a> for the article and the <a href="https://github.com/bhusalb/privacy-preserving-icl">repository</a> for implementation details. General statements about differential privacy or composition should also cite their foundational sources.</p>]]></content><author><name>Bishnu Bhusal</name></author><category term="research"/><category term="differential-privacy"/><category term="language-models"/><category term="in-context-learning"/><summary type="html"><![CDATA[How clipped logits, public context, and private token sampling can produce reusable ICL demonstrations, with careful accounting for privacy boundaries.]]></summary></entry><entry><title type="html">DipApprox: verifying differential privacy with Gaussian noise</title><link href="https://bishnubhusal.com.np/blog/2026/dipapprox-gaussian-differential-privacy/" rel="alternate" type="text/html" title="DipApprox: verifying differential privacy with Gaussian noise"/><published>2026-08-26T10:00:00-06:00</published><updated>2026-08-26T10:00:00-06:00</updated><id>https://bishnubhusal.com.np/blog/2026/dipapprox-gaussian-differential-privacy</id><content type="html" xml:base="https://bishnubhusal.com.np/blog/2026/dipapprox-gaussian-differential-privacy/"><![CDATA[<p>A program can add Gaussian noise and still fail its intended differential privacy guarantee. The answer depends on what the program releases, how its branches interact, and how it reuses random values. Establishing privacy therefore requires reasoning about the complete computation.</p> <p>In our CCS 2025 paper, <a href="/publications/bhusal2025ccs/"><em>Approximate Algorithms for Verifying Differential Privacy with Gaussian Distributions</em></a>, we develop a way to automate that reasoning for a defined class of programs. Our tool, <strong>DipApprox</strong> (styled <strong>DiPApprox</strong> in the paper), computes probability intervals with certified error bounds and uses them to prove privacy, find a violation, or report that the current precision is insufficient.</p> <p>I worked on this paper with <strong>Rohit Chadha, A. Prasad Sistla, and Mahesh Viswanathan</strong>. This visual walkthrough explains the method, its limits, and selected results. <a href="/assets/pdf/ccs25.pdf">Read the paper</a>, <a href="https://github.com/bhusalb/approximate-dp">browse the code</a>, or <a href="/publications/bhusal2025ccs/cite.bib">download the citation</a>.</p> <h2 id="from-a-randomized-program-to-a-privacy-answer">From a randomized program to a privacy answer</h2> <p>Consider a program that samples one noisy threshold and compares several independently perturbed queries against it. Even though the noise draws are independent, the comparison outcomes share the threshold. Computing the probability of a particular output sequence requires accounting for that shared random value.</p> <p>This is the challenge behind examples such as Gaussian variants of the <strong>Sparse Vector Technique (SVT)</strong>. SVT answers threshold questions while limiting how many positive answers it releases. The program’s output is discrete, but the random choices leading to it range over the real line.</p> <p>DipApprox follows the program’s execution paths, expresses their probabilities as integrals, and encloses those probabilities in intervals. It then checks the differential privacy inequalities using the bounds.</p> <figure> <img src="/assets/img/research/dipapprox-verification-pipeline.svg" width="640" height="820" class="img-fluid" loading="lazy" data-zoomable="" alt="DipApprox pipeline: a program and finite inputs produce execution paths, bounded integrals and tail bounds, probability intervals, and privacy-gap bounds, ending in DP, Not_DP, or Unknown."/> <figcaption><strong>Figure 1.</strong> The verification pipeline. Both integration error and probability in the tails remain accounted for in the final bounds.</figcaption> </figure> <p>The formal program class, <strong>DiPGauss</strong>, has finite input and output domains and is loop-free. Fixed bounded loops can be unrolled. Its presented syntax includes Gaussian and Laplace sampling; the underlying probability-approximation argument extends to suitable distributions with computable densities and finite means and variances. The prototype has additional restrictions, including support for comparisons among sampled values. These assumptions define what a successful check establishes.</p> <h2 id="why-a-gaussian-tail-cannot-simply-be-ignored">Why a Gaussian tail cannot simply be ignored</h2> <p>For an elementary example, suppose a program releases whether a query value plus Gaussian noise exceeds a fixed threshold:</p> \[b=\mathbf{1}\{q+Z&gt;T\},\qquad Z\sim\mathcal{N}(0,\sigma^2).\] <p>The probability of releasing 1 is an integral of the Gaussian density from \(T-q\) to infinity. More complicated programs introduce multiple random values and branch conditions, producing nested integrals. A numerical estimate alone is insufficient when a privacy inequality is close to its boundary.</p> <p>Our approach separates a bounded integration region from its tails. It computes the bounded-region contribution with an error bound, then adds a bound on the probability outside that region. For multiple samples, the tail contribution accounts for the event that at least one draw falls outside its allowed window.</p> <figure> <img src="/assets/img/research/dipapprox-gaussian-tails.svg" width="640" height="490" class="img-fluid" loading="lazy" data-zoomable="" alt="A standard Gaussian split at minus two and plus two standard deviations: about 95.45 percent of its mass is in the center, and 4.55 percent is in the two tails combined. The tail mass must be bounded, not discarded."/> <figcaption><strong>Figure 2.</strong> An illustrative integration window, chosen to make the tails visible. The paper's experiments use a wider Gaussian window of four standard deviations, not the two-standard-deviation window shown here. Tail truncation error is a numerical quantity, separate from the privacy parameter δ.</figcaption> </figure> <p>The theory uses tail inequalities, including Chernoff and Chebyshev bounds. The implementation uses <strong>FLINT</strong> for rigorous arithmetic and integral computation. A computed value is represented by a ball enclosure—a midpoint together with an error radius—rather than an unqualified floating-point estimate.</p> <p>The resulting probability interval contains the true probability. The paper’s approximation interface can request an interval of width at most \(2^{-\rho}\), where increasing \(\rho\) asks for finer precision. Numerical approximation therefore does not weaken a certified privacy conclusion: uncertainty remains explicit in the bounds.</p> <h2 id="checking-privacy-without-enumerating-every-output-event">Checking privacy without enumerating every output event</h2> <p>Differential privacy compares the program’s output distributions on neighboring inputs. Let \(p_u(o)\) denote the probability of output \(o\) on input \(u\). For a fixed privacy budget \(\varepsilon_{\mathrm{prv}}\), define the directed privacy gap</p> \[\Delta(u,u')= \sum_o\max\left\{ p_u(o)-e^{\varepsilon_{\mathrm{prv}}}p_{u'}(o),\;0 \right\}.\] <p>The program satisfies \((\varepsilon_{\mathrm{prv}},\delta)\)-differential privacy when this gap is at most \(\delta\) for every required ordered adjacent pair. With symmetric adjacency, both directions matter.</p> <p>Why sum only positive terms? The output event that maximizes the privacy violation includes exactly the outputs with positive contributions. This replaces checking every subset of the finite output space with a sum over individual outputs. Lemma 2 in the paper establishes the equivalence.</p> <p>DipApprox computes lower and upper bounds on this gap. For each pair, an upper bound at or below \(\delta\) proves the inequality; a lower bound above \(\delta\) proves a violation. An interval crossing the boundary is inconclusive at the current precision. Equivalently, the largest gap over all required pairs must be at most \(\delta\); the figure illustrates bounds on that maximum.</p> <figure> <img src="/assets/img/research/dipapprox-privacy-intervals.svg" width="640" height="500" class="img-fluid" loading="lazy" data-zoomable="" alt="Illustrative bounds on the maximum privacy gap against delta equal to 0.10: 0.04 to 0.08 certifies privacy, 0.12 to 0.16 certifies a violation, and 0.08 to 0.13 is inconclusive."/> <figcaption><strong>Figure 3.</strong> Three possible relationships between a certified interval and the privacy boundary. The numbers illustrate the decision rule; they are not experimental measurements or recommended privacy settings. A program-wide DP answer requires checking every pair in the specified adjacency relation; one violating pair is enough for Not_DP.</figcaption> </figure> <p>The paper distinguishes the mechanism’s noise-controlling parameter \(\varepsilon\) from its claimed privacy budget \(\varepsilon_{\mathrm{prv}}\). They need not be equal. A verification run fixes both, together with \(\delta\) and the adjacency relation.</p> <h2 id="what-almost-decidable-means">What “almost decidable” means</h2> <p>The qualifier concerns termination at exact boundaries. For a fixed program, noise parameter, privacy budget, and adjacency relation, the theory identifies a finite set of critical \(\delta\) values. Away from that set, sufficiently precise probability bounds can decide the privacy question. At a critical value, continued refinement may remain inconclusive.</p> <p>The answers <strong>DP</strong> and <strong>Not_DP</strong> are sound under the model’s assumptions. <strong>Unknown</strong> preserves that soundness when the current bounds cannot resolve the inequality. It is neither a privacy certificate nor evidence of a violation. This is also distinct from <em>approximate differential privacy</em>, where \(\delta\) appears in the guarantee itself.</p> <h2 id="making-the-integrals-practical">Making the integrals practical</h2> <p>Nested integration can dominate runtime. The paper uses a dependency graph of integration limits to identify opportunities to separate integrations and reduce nesting while preserving their values. For the studied SVT-Gauss expressions, this optimization limits maximum nesting depth to three, independently of the number of queries.</p> <figure> <img src="/assets/img/research/dipapprox-optimization.svg" width="640" height="620" class="img-fluid" loading="lazy" data-zoomable="" alt="Paper Table 2, SVT-Gauss with five queries and one selected adjacent pair: optimized integration took 7.9 seconds and reduced maximum nesting depth from six to three; unoptimized integration exceeded the 600-second timeout."/> <figcaption><strong>Figure 4.</strong> A result from Table 2 of the paper: SVT-Gauss, N = 5, one selected adjacent pair, ε = 0.5, ε_prv = 1.24, and δ = 0.01. The optimized runtime averages three runs on a 1.4 GHz quad-core Intel Core i5 Mac with 8 GB RAM. The unoptimized result is a timeout, not a measured completion time of 600 seconds.</figcaption> </figure> <p>The experiments also distinguish <strong>checking one pair</strong> from <strong>verifying all pairs in a finite domain</strong>. For SVT-Gauss with five queries, Table 1 reports 76.7 seconds for all pairs of binary input vectors under the experiment’s adjacency relation. For 25 queries, one selected pair took 441.3 seconds, while the all-pair run exhausted memory. In this benchmark, every pair of vectors in \(\{0,1\}^N\) is considered adjacent; the selected pair is the all-zero vector and the vector with only its final entry set to one.</p> <p>The tool also detected violations in both Gaussian SVT leaky variants at the parameter settings reported in Table 1. These results demonstrate both proof and falsification on the benchmark programs. They also expose a practical limit: reducing integral depth does not remove the growth in the number of input combinations. The supported mathematical model is not a verification of arbitrary deployed Python or C++ implementations, including their floating-point sampling behavior.</p> <h2 id="explore-the-artifact">Explore the artifact</h2> <p>The <a href="https://github.com/bhusalb/approximate-dp">code repository</a> contains the Python/C++ implementation, examples, and reproduction scripts. For the version associated with CCS 2025, use the <a href="https://doi.org/10.5281/zenodo.16930793">archived artifact on Zenodo</a>.</p> <p>The repository documents this Docker workflow:</p> <div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git clone https://github.com/bhusalb/approximate-dp.git
<span class="nb">cd </span>approximate-dp
docker build <span class="nb">.</span> <span class="nt">-t</span> dpapprox
docker run <span class="nt">--rm</span> <span class="nt">-it</span> dpapprox
</code></pre></div></div> <p>Inside the container, start with <code class="language-plaintext highlighter-rouge">python3 src/main.py --help</code> to inspect the verification options. The documented benchmark entry points are <code class="language-plaintext highlighter-rouge">scripts/benchmark.py</code> and <code class="language-plaintext highlighter-rouge">scripts/benchmark_unoptimized.py</code>; <code class="language-plaintext highlighter-rouge">scripts/table_generator.py</code> generates Tables 1 and 2. Consult the <a href="https://github.com/bhusalb/approximate-dp/blob/master/README.md">artifact README</a> for the current instructions and select the program, parameters, and input pairs deliberately when interpreting a result.</p> <h2 id="paper-and-citation">Paper and citation</h2> <p><strong>Bishnu Bhusal, Rohit Chadha, A. Prasad Sistla, and Mahesh Viswanathan.</strong> “Approximate Algorithms for Verifying Differential Privacy with Gaussian Distributions.” <strong>ACM CCS 2025</strong>, pp. 1439–1453. <a href="https://doi.org/10.1145/3719027.3765043">DOI: 10.1145/3719027.3765043</a>.</p> <p>The <a href="/assets/pdf/ccs25.pdf">author-hosted extended paper</a> contains the definitions, proofs, and experimental details used here. See Sections 5–6 for the decision procedure and probability approximation, and Section 7 and Tables 1–2 for the results. <a href="/publications/bhusal2025ccs/cite.bib">Download BibTeX</a> or <a href="/publications/bhusal2025ccs/cite.ris">RIS</a>.</p> <p>Cite this work when using its probability-approximation method, studying automated privacy verification for its supported Gaussian-sampling programs, or comparing against DipApprox. For foundational differential privacy definitions and composition, see Dwork and Roth’s <a href="https://www.cis.upenn.edu/~aaroth/Papers/privacybook.pdf"><em>The Algorithmic Foundations of Differential Privacy</em></a>.</p>]]></content><author><name>Bishnu Bhusal</name></author><category term="research"/><category term="differential-privacy"/><category term="formal-verification"/><category term="gaussian-mechanisms"/><summary type="html"><![CDATA[Inside our CCS 2025 paper: how DipApprox uses certified integration, Gaussian tail bounds, and probability intervals to prove or refute differential privacy.]]></summary></entry></feed>